
How to hire big data engineers: a step-by-step guide
A practical guide to hiring big data engineers: the role, skills to test, a JD template, interview questions, pay benchmarks and onboarding.
Knowing how to hire big data engineers starts with one fact: the role is defined by your data stack, not by the job title. Big data engineers design, build and run the systems that collect, store and process very large data sets, using tools such as Spark, Kafka, Hadoop and cloud data platforms. The best hiring processes test that work directly before anyone spends an hour in an interview.
TL;DR / Key Takeaways
- To hire big data engineers, define your stack and data volumes, write a specific job description, test skills before interviews, run a structured technical interview, check references and make a benchmarked offer.
- Test six areas: distributed processing (Spark, Hadoop), streaming (Kafka), programming (Python, Scala or Java), SQL and data modeling, cloud platforms and problem solving.
- A short skills test before the first live interview is the fastest way to separate real pipeline experience from keyword-heavy resumes.
- The US Bureau of Labor Statistics puts the median pay for database architects, the closest official benchmark, at $139,500 (May 2025). Senior and cloud specialists earn more.
- Name exact tools in the job description ("Spark on Databricks", "Kafka to Snowflake"). Vague tool lists attract generalists.
- Most teams can go from job post to signed offer in 3 to 6 weeks with 3 interview rounds and a fast offer.
 ChatGPT
 Gemini
 Claude
 Grok
 Perplexity
What does a big data engineer do?
A big data engineer builds and maintains the infrastructure that moves data from source systems into storage and analytics, at a scale that one database server cannot handle. Read the big data glossary entry for the basics of the term itself.
Day to day, the work usually covers:
- Data pipelines: Batch and streaming pipelines that ingest, clean and load data from apps, events, logs and third-party tools, written in Python, Scala or Java.
- Distributed processing: Jobs on Spark, Hadoop MapReduce, Hive or Flink that split work across many machines.
- Storage: Data lakes, data warehouses and NoSQL stores such as Cassandra or MongoDB, with data models built for performance.
- Data quality and governance: Validation rules, monitoring and lineage so analysts and models get correct data.
- Security and privacy: Encryption, access control and compliance with privacy rules for sensitive data.
- Collaboration: Turning requests from data scientists, analysts and product teams into reliable data products.
- Performance and cost: Tuning jobs, partitioning data and keeping cloud spend under control.
Big data engineers are a specialist branch of data engineering. A general data engineer may spend most of the day on SQL and warehouse models; a big data engineer spends more time on distributed systems, streaming and terabyte-scale performance problems. Companies in financial services, healthcare, retail, e-commerce, SaaS and transportation hire for the role most often.
How to hire big data engineers in 8 steps
Hiring big data engineers works best as an assessment-led process: agree on the stack, attract the right applicants with a specific job description, and test real skills before live interviews. The eight steps below combine what works across technical hiring teams.
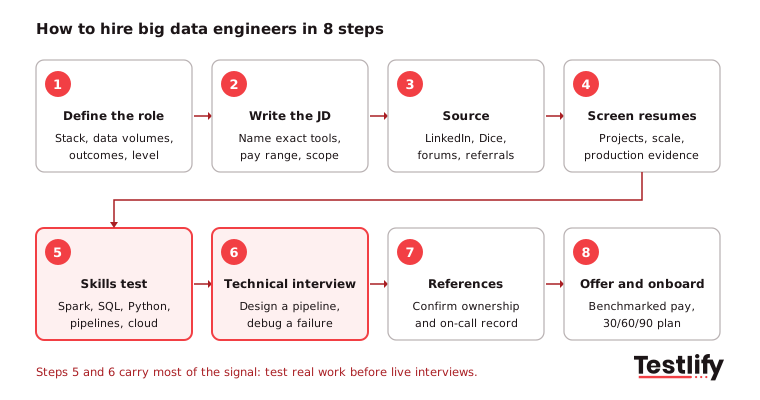
- Define the role: Agree with your data and analytics leads on the exact tools (for example, Spark on Databricks or EMR, Kafka or Kinesis), the data volumes, the pipelines the hire will own and the seniority level. Decide whether you need a full-time hire or a contractor for a fixed migration.
- Write a specific job description: List responsibilities, named technologies, cloud environment and a pay range. Engineers scan for their exact stack, so specificity improves self-selection.
- Source in the right places: Post on LinkedIn and tech job boards, reach out to passive candidates, ask current engineers for referrals and engage data engineering communities.
- Screen resumes for evidence: Look for production pipelines, data volumes, on-call ownership and migrations, not long tool lists. Public repositories and documented projects are strong signals.
- Run a skills test before interviews: A 30 to 45 minute assessment covering big data concepts, SQL, a programming language and problem solving gives you comparable results for every applicant.
- Hold a structured technical interview: Use a structured interview with the same questions and scorecard for every candidate, plus a pipeline design or debugging exercise.
- Check references: Confirm the systems the candidate owned, the scale they worked at and how they handled incidents.
- Make the offer and onboard: Benchmark pay, move within 24 to 48 hours of the final round, and share a 30/60/90-day plan with clear pipeline ownership milestones.
Pro tip: Before you post the role, share a sanitized diagram of one of your real pipelines with the hiring panel and agree on the two bottlenecks a strong candidate should spot. Use the same diagram in the interview. In under 15 minutes it shows both technical depth and how clearly the candidate explains trade-offs.
What skills should you test in a big data engineer?
Big data engineer skills fall into six areas: distributed processing, streaming, programming, SQL and data modeling, cloud platforms and problem solving. Soft skills matter too, because big data engineers explain complex systems to non-technical stakeholders every week. The table maps each skill to what to check and a matching Testlify test.
Skill area | What to check | Testlify test |
|---|---|---|
Distributed processing | Spark jobs, partitioning, shuffles, Hadoop and Hive basics | Big data, Spark, Hadoop |
Streaming | Kafka topics, consumer groups, exactly-once delivery, late data | Kafka |
Programming | Clean, testable pipeline code in Python, Scala or Java | Python, Scala |
SQL and data modeling | Joins, window functions, schemas for lakes and warehouses | SQL, Data modeling |
Cloud platforms | AWS, Azure or Google Cloud data services, cost control | Cloud computing |
NoSQL storage | Data models and indexing in Cassandra, MongoDB or HBase | NoSQL |
Problem solving | Debugging a failing job, weighing trade-offs | Problem solving |
Communication | Explaining a design to analysts and managers | Communication |
Language choice should follow your stack. According to the Stack Overflow Developer Survey 2025, 58.6% of developers use SQL and 57.9% use Python, while Scala sits at 2.6%. If your Spark code base is in Scala, test Scala; otherwise Python and SQL cover most of the work. The same survey found AWS (43.3%) ahead of Azure (26.3%) and Google Cloud (24.6%), which matches what most job descriptions ask for.
Beyond tools, look for:
- Analytical thinking: Reading a slow job plan or a skewed data distribution and knowing where to look first.
- Attention to detail: Catching silent data loss, duplicate records and schema drift before they reach dashboards.
- Adaptability: Big data stacks change every few years. Engineers who learn new tools keep technical debt down.
- Ownership: Owning pipelines in production, including monitoring and incident response.
Expectations also change with seniority:
Level | Typical experience | What to assess |
|---|---|---|
Junior | 0 to 2 years | SQL, one language, basic Spark, learning speed |
Mid-level | 3 to 5 years | Building and tuning pipelines, streaming basics, cloud services |
Senior | 5 to 8 years | Architecture choices, cost and performance trade-offs, mentoring |
Lead or architect | 8+ years | Platform strategy, vendor choices, team design, governance |
Degrees in computer science, data science or information systems are common, and certifications such as the Databricks, AWS or Google Cloud data engineering credentials can help. Treat both as signals, not filters: hands-on pipeline experience and test results say more.
How do you write a big data engineer job description?
A big data engineer job description should name your exact stack, the data volumes and pipelines the hire will own, the level, and a pay range. Generic phrases like "big data tools" attract generalists; "Spark on AWS EMR feeding Snowflake" attracts the engineers you want. Start from the template below or the full big data engineer job description template.
Job title: Big Data Engineer
Department and reporting line: Data platform team, reporting to the Head of Data Engineering (or Director of Technology)
Location: [City, State] / hybrid / remote
Overview: As a Big Data Engineer, you will design, build and run the large-scale data processing systems behind our analytics and machine learning products. You will own pipelines from ingestion through to clean, reliable data, working closely with data scientists, analysts and product teams.
Responsibilities:
- Design, build and deploy batch and streaming pipelines using [Spark, Kafka, Airflow] on [AWS / Azure / Google Cloud].
- Design data models for our data lake and warehouse that balance performance, cost and ease of use.
- Implement data validation, cleansing and quality monitoring across the data lifecycle.
- Tune jobs and storage for performance and cloud cost.
- Apply data security, access control and compliance measures to sensitive data.
- Troubleshoot and resolve pipeline and infrastructure incidents.
- Work with data scientists, analysts and business stakeholders to turn requirements into data products.
Requirements:
- [3+ / 5+] years building data pipelines in production.
- Hands-on experience with Spark and at least one of Hadoop, Hive, Kafka or Flink.
- Strong Python, Scala or Java, and advanced SQL.
- Experience with distributed computing and data partitioning.
- Knowledge of data modeling and database design for lakes, warehouses and NoSQL stores.
- Experience with a major cloud platform and its data services.
- Understanding of data governance and security practices.
- Clear communication with technical and non-technical colleagues.
Benefits: [Salary range], learning budget, flexible or remote work, and the chance to work on data at real scale.
To apply: Send your resume and a short note on the largest pipeline you have owned to [email or application link].
Where can you find big data engineers?
Big data engineers are found on professional networks, tech job boards and in data engineering communities, and the strongest senior candidates usually come from direct outreach and referrals rather than inbound applications. Use a mix:
- LinkedIn: The largest pool. Filter by Spark, Kafka, Databricks or Airflow in skills and projects, and message engineers who engage with data engineering content.
- Indeed: Wide reach and volume, best for mid-level roles where funnel size matters.
- Dice: Focused on technology roles, with a resume database that skews toward experienced engineers.
- Glassdoor: Candidates research employers here. A company profile that names your data stack improves inbound quality.
- Monster: Useful for regions or industries that tech-focused boards reach less well.
- Communities: The r/dataengineering and r/bigdata subreddits, dbt and Apache project communities, local meetups and conferences such as Spark and cloud summits. Lead with the technical problem you are solving, not a hiring pitch.
- Referrals: Current engineers know who has run real distributed systems. Referral hires tend to understand the job before day one.
Key takeaway: For senior roles, outreach that names a real problem ("we are moving our Kafka to Spark to Snowflake pipeline to handle 10x volume") gets more replies than a generic opportunity message.
Which skills tests should you use for big data engineers?
Skills tests for big data engineers should cover distributed systems knowledge, coding ability and analytical reasoning, the three areas that show whether someone can run production pipelines. A combined assessment taken before the first live interview gives every applicant the same questions and gives you comparable scores instead of resume claims.
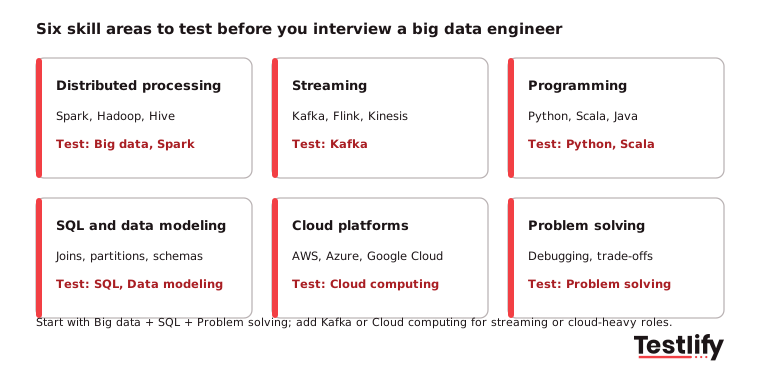
A practical starting stack:
- Core: Big data + SQL + Problem solving.
- Streaming roles: Add Kafka.
- Cloud-heavy roles: Add Cloud computing or a cloud data service test.
- Broad data platform roles: Use the Testlify data engineer test as the base and add Spark or Kafka.
Keep the whole assessment to 30 to 45 minutes. For senior roles, add a short practical task, such as fixing a slow Spark job or designing a fault-tolerant Kafka pipeline, rather than a multi-day take-home that strong candidates skip.
Testlify supports this with a library of 3,500+ tests, coding questions in 45+ programming languages, an AI test builder that turns a job description into an assessment, and 20+ anti-cheating and proctoring checks (see anti-cheating and proctoring). Scores sync back to 100+ ATS and HRIS tools through Testlify integrations.
What interview questions should you ask big data engineers?
Interview questions for big data engineers should test how candidates design, debug and explain distributed data systems, not just whether they know definitions. Use the same questions and a scorecard for every candidate. For a longer bank, see these interview questions for big data engineers.
What is the difference between batch and stream processing, and how do you choose?
What to listen for: Clear definitions, latency and cost trade-offs, and a real use case for each (nightly reporting versus fraud detection).
How would you design a fault-tolerant data pipeline with Apache Kafka?
What to listen for: Replication, consumer groups, offsets, idempotent writes, dead-letter handling and monitoring.
What are the key differences between Hadoop and Spark?
What to listen for: Disk versus in-memory processing, performance, APIs, and when Hadoop still makes sense in an existing estate.
How do you partition data in HDFS or a data lake, and what factors drive your choice?
What to listen for: Query patterns, file sizes, cardinality and the cost of too many small files.
What is data skew, and how do you detect and fix it?
What to listen for: Spotting skew in job metrics, then salting keys, repartitioning or broadcast joins.
How would you optimize a slow Hive or Spark SQL query?
What to listen for: Reading the execution plan, partition pruning, file formats such as Parquet, join strategies and caching.
How do SQL joins behave at big data scale?
What to listen for: Inner, left, right and full outer joins, plus shuffle cost and broadcast joins in Spark.
How do you choose a compression format for big data workloads?
What to listen for: Trade-offs between gzip, Snappy and LZO, splittability, and the effect on CPU and storage.
When would you use a NoSQL database like Cassandra, and what are its limits?
What to listen for: Write-heavy workloads, partition keys, query-first modeling and weak support for ad hoc joins.
How would you design a distributed cache for a data platform?
What to listen for: Tools such as Redis or Apache Ignite, eviction and expiry policies, and consistency trade-offs.
Add five general questions to cover experience and ways of working:
- Walk us through the most complex data project you have owned. What scale did it run at?
- How do you make pipelines faster and cheaper without breaking them?
- What steps do you take to keep data quality high in a big data environment?
- Tell us about a time a pipeline you owned produced wrong results. How did you find and fix it?
- How do you keep up with changes in big data tools?
How much does it cost to hire a big data engineer?
The cost to hire a big data engineer is mostly salary, and US pay for the role typically starts around $100,000 and passes $200,000 for senior and cloud specialists. The US Bureau of Labor Statistics has no separate data engineer category, so the closest official benchmark is database architects.
According to BLS data on database architects, the median annual wage was $139,500 in May 2025. The lowest 10% earned less than $86,240 and the highest 10% more than $204,000. BLS data from the same page puts the database administrator median at $104,620 and projects 9% employment growth for database architects over the decade.
Cost item | What to plan for |
|---|---|
Base salary | Benchmark against BLS and current local data; senior and streaming specialists sit at the top of the range |
Recruiting time | Sourcing, screening and 3 interview rounds, usually 3 to 6 weeks |
Interview hours | Engineers' time on panels; a skills test first cuts the number of interviews |
Onboarding | Access, environment setup and 1 to 3 months to full productivity |
Contract alternative | A contractor can fit a fixed migration; a permanent hire fits ongoing platform ownership |
Review pay benchmarks at least once a year and before every senior offer. Big data engineers usually have several offers at once, and a low first number is the most common reason a late-stage candidate walks away.
What mistakes should you avoid when hiring big data engineers?
The most common mistakes when hiring big data engineers are vague job descriptions, too much weight on degrees, skipping a skills test, and slow offers. Avoid these:
- Vague role definition: "Big data tools" in the job description brings generalists. Name the stack and the pipelines.
- Overvaluing degrees and years: Academic qualifications help, but production experience and test results show what someone can do.
- Hiring for the wrong framework: Deep Hadoop experience does not guarantee Spark or streaming skills. Test the tools you run.
- Skipping the skills test: Resumes hide the gap between claimed and real experience.
- Too many rounds: More than 3 or 4 interviews loses strong candidates to faster companies.
- Ignoring communication: Big data engineers explain designs to non-technical teams. Poor communication creates friction across the data organization.
- No scorecard: Without agreed criteria, interviewers compare gut feelings, not evidence.
- Slow or low offers: Decide within 48 hours of the final round and make a benchmarked offer.
- Poor candidate experience: Give timely feedback and clear next steps. Engineers share hiring experiences in their communities.
Background checks need care too. The EEOC and FTC guidance on background checks says employers must get written consent before ordering a report and must apply the same standards to everyone. Check references with former managers to confirm the systems the candidate owned and how they handled incidents.
How should you onboard a new big data engineer?
Onboarding a new big data engineer works best as a 30/60/90-day plan with clear pipeline ownership milestones, so the hire becomes productive fast and understands your data, tools and standards.
- First 30 days: Access to environments, a walkthrough of the data platform and key pipelines, and a small fix shipped to production.
- Days 31 to 60: Ownership of one pipeline, including monitoring and on-call, plus a first improvement to performance or data quality.
- Days 61 to 90: Ownership of a larger project, such as a migration or new data source, and a review against the goals set at hiring.
Pair the new hire with a senior engineer, document your standards for code review, testing and data quality, and give a learning budget. Big data tools change often, and ongoing training keeps both skills and retention up.
What outreach and rejection emails should you send?
Outreach and rejection emails for big data engineers should be short, personal and specific about your stack. Engineers reply to messages that mention their actual tools and a real problem, and they remember how a rejection was handled.
Outreach email:
Subject: Big Data Engineer at [Company]: [one-line data problem]
Hi [Name],
I saw your work on [project or stack, for example Spark pipelines on AWS]. At [Company], we are [real problem, for example moving our Kafka to Spark to Snowflake pipeline to handle 10x volume], and we are hiring a Big Data Engineer to own it. The role works with [tools] and reports to [title]. Would you be open to a 20-minute call next week?
Best regards, [Your name], [Title], [Company]
Follow-up email (5 to 7 business days later):
Subject: Re: Big Data Engineer at [Company]
Hi [Name], following up on my note about the Big Data Engineer role. One more detail: [new fact, such as team size, data volume or tech choice]. If now is not the right time, I would be glad to stay in touch.
Interview invitation:
Subject: Interview invitation: Big Data Engineer at [Company]
Hi [Name], thank you for your time so far. We would like to invite you to the next stage: a [length] technical interview with [panel], covering [pipeline design / debugging]. Please share times that work for you this week.
Rejection email (send within 48 hours of the decision):
Subject: Your application for Big Data Engineer at [Company]
Dear [Name],
Thank you for applying for the Big Data Engineer role at [Company] and for the time you put into the process. After careful review, we have decided to move forward with candidates whose experience more closely matches this role's current needs. [Optional: one specific strength we noted.] We would welcome an application for future openings that fit your skills.
Best wishes, [Your name]
Ready to test big data engineers before you interview?
Testlify lets you build a big data engineer assessment from your job description, combine Big data, Spark, Kafka, SQL and Python tests, and get a ranked shortlist with proctored, comparable scores. Start a 7-day free trial with no credit card, or book a demo to see it with your own role.
Frequently asked questions about how to hire big data engineers
Related resources
View all
Candidate assessment
The Ultimate Guide to Hiring a Top-Notch Network Engineer
Candidate assessment
How to hire a system administrator
Candidate assessment
How Testlify helps companies reduce bias in hiring
Candidate assessment
Advanced Excel Assessment: How to Test Candidate Skills (2026)
Candidate assessment
Project management skills assessment guide
Candidate assessment
Cognitive diversity at workplace: what is it and why is it important
Get started.
Hire on proof, not resumes.
Run your first skills-based assessment free — no credit card required.