
50 data scientist interview questions to ask in 2026
50 interview questions for data scientist roles, grouped by skill, with answer guidance, coding tasks, sample answers and a scoring rubric.
Data scientist interview questions are the questions a hiring team uses to check whether a candidate can turn messy data into decisions: statistics, machine learning, coding, data handling, business sense and real project experience. The best ones come with a clear standard for a strong answer, so two interviewers reach the same call.
That standard matters because the role is hard to judge from a resume. A candidate can list every algorithm and still freeze when asked which metric the business cares about. Demand is also climbing: the US Bureau of Labor Statistics projects data scientist jobs to grow 35% from 2025 to 2035, with about 24,800 openings a year, so every weak interview costs you a candidate someone else will hire.
Below are 50 questions in seven groups, each with what a strong answer covers, plus coding tasks, sample answers for the behavioral round and a scoring rubric you can use even if you are not a data scientist.
TL;DR / Key Takeaways
- Good data scientist interview questions test statistics, machine learning, coding, data handling, business sense and real project experience. Most 2026 roles add modern AI and MLOps skills.
- Send a skills test before the interview. The interview should confirm a strong candidate, not discover a weak one.
- Ask 8 to 12 questions per interview, not all 50. Pick from each group to match the role and seniority.
- Juniors should be judged on fundamentals and clean code; seniors on trade-offs, production models and business impact.
- Score every answer on a 1 to 4 scale and have two interviewers score on their own before they compare.
- The biggest red flag is a candidate who can name every model but cannot say which metric the business cares about or what their work changed.
 ChatGPT
 Gemini
 Claude
 Grok
 Perplexity
What should data scientist interview questions test in 2026?
Data scientist interview questions should test five core skill areas, with the weight set by the job: statistics, machine learning, coding and data handling, business sense, and modern tooling such as large language models and MLOps. Statistics and machine learning fundamentals still matter most, but more real data work now touches AI systems.
Pay reflects how scarce the full mix is. The US Bureau of Labor Statistics puts the median data scientist salary at $120,230 a year (May 2025). Map your questions to the table below and weight the rows that match the job description.
Skill area | What to assess | A signal it is real, not rehearsed |
|---|---|---|
Statistics and probability | Hypothesis testing, p-values, distributions, A/B tests | They say what a p-value does not mean, not just the textbook definition |
Machine learning | Supervised vs unsupervised, overfitting, bias-variance, evaluation metrics | They pick a metric to fit the business cost, not just report accuracy |
Coding and data handling | Python, Pandas, SQL, cleaning messy real-world data | They handle missing values and edge cases without being prompted |
Business sense and communication | Turning a model into a decision, explaining it to non-experts | They start by asking what question the business is really trying to answer |
Modern tooling (LLMs and MLOps) | Evaluating LLM features, deploying and monitoring models | They can say why a deployed model drifts and how they would catch it |

When should you ask data scientist interview questions?
Data scientist interview questions work best after a skills test, not before. Invite applicants to a short role-based assessment first, then bring the top scorers to the interview. That order saves your team from screening dozens of resumes by hand and keeps strong candidates from waiting in a slow process.
A pre-interview skills assessment shows whether a candidate can write working code and reason about data before anyone spends an hour on a call. The interview then probes judgment, problem-solving and how someone works with non-technical teams.
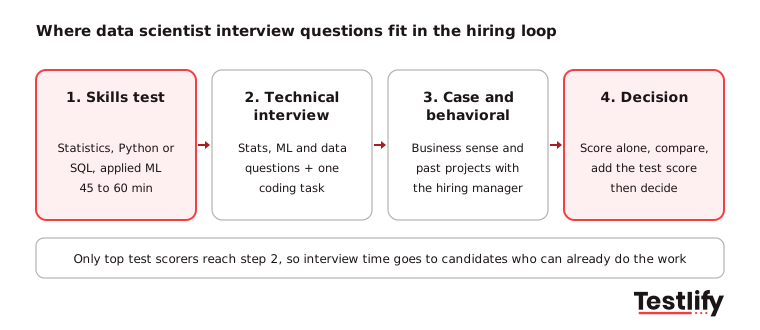
A simple loop for most data roles:
- Skills test: A 45 to 60 minute assessment covering statistics, Python or SQL and applied machine learning, such as the Testlify data scientist test.
- Technical interview: 45 to 60 minutes on the statistics, machine learning and data handling questions below, plus one coding task.
- Case and behavioral interview: 45 minutes on business sense and past projects, ideally with the hiring manager.
- Calibrated decision: Interviewers score on their own, compare, and combine the scores with the test result.
Which statistics and probability questions should you ask a data scientist?
Statistics questions should show whether a candidate can reason about uncertainty, not just recite formulas. These eight interview questions for data scientist roles cover the concepts behind every experiment and model. Pair them with the statistics and probability test if the role is analytics-heavy.
1. What is the significance of a p-value in hypothesis testing?
What a strong answer covers: A p-value is the probability of seeing results at least this extreme if the null hypothesis were true. A low value (often under 0.05) is evidence against the null. The best answers add what a p-value is not: the probability that the hypothesis is true, or a measure of effect size.
2. What is the difference between a Type I and a Type II error?
What a strong answer covers: A Type I error rejects a true null (a false positive); a Type II error misses a real effect (a false negative). Look for which one is costlier in a given business case and how they would trade them off.
3. How would you design an A/B test for a new checkout button?
What a strong answer covers: A clear success metric, a guardrail metric, random assignment, a sample size worked out from the smallest effect worth detecting, and a fixed run time. Red flag: Stopping the test the moment the result looks significant.
4. Explain the Central Limit Theorem and why it is useful.
What a strong answer covers: The distribution of sample means approaches a normal curve as the sample grows, whatever the population looks like. Look for why that lets you use normal-based inference, like confidence intervals, on real data.
5. How do you assess whether a dataset is normally distributed?
What a strong answer covers: Visual checks (Q-Q plots, histograms) and tests like Shapiro-Wilk. Look for why normality matters for some methods and what they would do when the data is clearly not normal.
6. What is multicollinearity, and how does it hurt a regression model?
What a strong answer covers: Highly correlated predictors inflate standard errors and make coefficients unstable and hard to read. Look for how they detect it, such as a VIF check, and what they do about it.
7. What is a confidence interval, and how would you explain one to a manager?
What a strong answer covers: A range built so that, over many repeated samples, a set share (say 95%) of such ranges would contain the true value. The plain-English version matters as much as the definition.
8. When would you use a non-parametric test?
What a strong answer covers: When the data breaks the assumptions of a t-test or ANOVA, for example small samples or heavily skewed data. Look for named tests such as Mann-Whitney U and a reason, not just a name.
Which machine learning questions reveal real skill?
Machine learning questions reveal real skill when they push past definitions into choices: which model, which metric, and why. These 14 questions cover the fundamentals every data scientist should own. For a deeper modeling role, borrow from our machine learning engineer interview questions.
9. What is the difference between supervised and unsupervised learning?
What a strong answer covers: Supervised learning trains on labeled data to predict an output; unsupervised learning finds structure in unlabeled data. A strong candidate gives real examples, like churn prediction for the first and customer segmentation for the second.
10. Explain the bias-variance tradeoff.
What a strong answer covers: Bias is error from a model that is too simple; variance is error from one that is too complex and memorizes noise. Look for the practical point: you tune model complexity and add data to find the balance. Red flag: Mixing up underfitting and overfitting.
11. What is overfitting, and how do you prevent it?
What a strong answer covers: The model nails the training data and fails on new data. Good answers name cross-validation, regularization, more data and early stopping, and explain when each one helps rather than listing all four.
12. What is cross-validation, and why use it?
What a strong answer covers: Splitting the data into folds to estimate how a model will do on data it has not seen. Look for k-fold, a holdout set kept aside until the end, and a clear reason it beats a single train/test split.
13. What is regularization, and when would you use it?
What a strong answer covers: A penalty added to the loss to keep coefficients small, which fights overfitting. Look for L1 (Lasso) versus L2 (Ridge) and why Lasso can zero out weak features.
14. How do you handle an imbalanced dataset?
What a strong answer covers: Resampling (oversampling the minority class or SMOTE), class weights and metrics smarter than accuracy. Red flag: Reporting 98% accuracy on a dataset where 98% of rows are one class.
15. Explain the difference between bagging and boosting.
What a strong answer covers: Bagging trains models in parallel on random subsets and averages them to cut variance; boosting trains them in sequence, each fixing the last one's errors, to cut bias. Look for random forests and gradient boosting as examples.
16. What are common evaluation metrics for a classification model?
What a strong answer covers: Accuracy, precision, recall, F1 and ROC-AUC. The real signal is knowing which to use when, like recall for disease screening and precision for fraud flags.
17. What is a confusion matrix, and how do you use it?
What a strong answer covers: A table of true and false positives and negatives that sums up a classifier's results. Look for the ability to read precision, recall and F1 straight off it.
18. How do you evaluate a regression model?
What a strong answer covers: R-squared, adjusted R-squared, MAE, MSE and RMSE, read in context. Ask what they would actually report to a non-technical manager.
19. Explain how a decision tree works, with its pros and cons.
What a strong answer covers: Splits on feature values into branches and leaves. Pros: easy to read and handles non-linear patterns. Cons: it overfits and is unstable. Look for the honest downside.
20. What is gradient descent, and how does it work?
What a strong answer covers: An optimization method that steps down the loss surface to shrink error. Look for the learning rate, convergence, and the batch, stochastic and mini-batch variants.
21. How do you decide which variables matter most in a predictive model?
What a strong answer covers: Domain knowledge first, then methods such as feature importance from tree models, permutation importance, recursive feature elimination or Lasso. The payoff is less overfitting and a model people can interpret.
22. What is data leakage, and how do you catch it?
What a strong answer covers: Information from the future or from the target sneaking into training features, which makes a model look far better offline than in production. Look for time-based splits, fitting preprocessing only on training data, and suspicion of results that look too good.
Pro tip: Ask one follow-up on every answer: "When would that approach fail?" Candidates who learned from real projects answer fast. Candidates who memorized a list go quiet.
What data handling and visualization questions should you ask?
Data handling questions should reveal how a candidate works before any model exists, because cleaning and exploring data takes up most of a real project. These eight questions combine data preparation, scale and visualization.
23. Walk me through how you would clean a messy dataset.
What a strong answer covers: Handle missing values, drop duplicates, fix data types, deal with outliers and scale features. Look for a methodical order and the point that clean data, not a fancy model, usually drives the result.
24. How do you handle missing or incomplete data?
What a strong answer covers: First ask why the data is missing: completely at random, at random, or not at random. That decides whether to drop rows, impute (mean, median, regression or multiple imputation) or use a model that tolerates gaps.
25. How do you detect and handle outliers?
What a strong answer covers: Spot them with box plots, Z-scores or the IQR method, then keep, cap or remove them based on whether they are real or errors. Red flag: A blanket "delete anything over three standard deviations" rule.
26. Explain exploratory data analysis (EDA) and why it matters.
What a strong answer covers: Summarizing and plotting a dataset to understand it before modeling: summary statistics, distributions and correlations. Look for the habit of looking at data before trusting it.
27. Describe a time you worked with a large, complex dataset. How did you approach it?
What a strong answer covers: Real scale (millions of rows or more), and tools such as Spark, SQL warehouses or sampling for early exploration. Look for how they kept results accurate while making the work fast.
28. Have you worked with unstructured data? What did you do with it?
What a strong answer covers: Text, images or logs, and the methods used to turn them into features, such as tokenization, embeddings or simple keyword rules. Look for a business result, not just a technique.
29. How do you decide which chart to use for a dataset?
What a strong answer covers: Match the chart to the data and the point: bar charts for categories, histograms for distributions, scatter plots for relationships. Look for a candidate who thinks about the audience first.
30. What makes a data visualization effective, or misleading?
What a strong answer covers: The right chart, clear labels, honest scales and colors that stay readable for colorblind viewers. Look for someone who has seen a misleading chart and can say why it misled.
Which questions test modern AI and MLOps skills?
Modern AI and MLOps questions test whether a data scientist can ship and run models, not just train them in a notebook. AI tools are now part of daily data work: the Stack Overflow Developer Survey 2025 found 84% of developers use or plan to use AI tools, up from 76% a year earlier, yet 46% distrust the accuracy of AI output. You want someone who uses these tools and checks them.
31. A model's results dropped three months after launch. How do you find out why?
What a strong answer covers: Check the data pipeline first, then data drift (inputs changed) and concept drift (the link between inputs and outcome changed). Look for monitoring dashboards, alert thresholds and a retraining plan.
32. How would you evaluate an LLM feature, such as a support chatbot?
What a strong answer covers: A labeled test set of real questions, task metrics (correct answers, refusals, harmful output), human review of a sample, and cost and latency tracking. Red flag: "We tried a few prompts and it looked good."
33. When would you use retrieval-augmented generation (RAG) instead of fine-tuning?
What a strong answer covers: RAG when answers depend on company documents that change often; fine-tuning when you need a set style or format on a narrow task. Look for retrieval quality checks, not just the model.
34. How do you use AI coding assistants in your work, and how do you check their output?
What a strong answer covers: Honest, specific use (boilerplate, SQL drafts, docs) plus tests, code review and spot checks on results. Look for someone who can explain every line they ship.
Screen these skills before the call with the GenAI and LLMOps test.
Which coding tasks should a data scientist complete in an interview?
Coding tasks should show whether a candidate can actually write the code, because talking about analysis is not the same as doing it. Give these five tasks in a shared editor or a short take-home, and watch how they handle the parts that are easy to skip, like an empty list or a tie.
35. Write a Python function to return the mean and median of a list of numbers.
What to look for: Correct math, clean sorting for the median, and an empty-list guard so it does not crash.
36. Write a SQL query to return the top three highest salaries from an employees table.
What to look for: ORDER BY with LIMIT, or a window function such as DENSE_RANK, and a candidate who asks whether ties should count.
37. Write a Python function to remove duplicates from a list while keeping order.
What to look for: Comfort with sets and lists, and a loop that keeps the original order instead of just calling set().
38. Use Pandas to filter the rows of a DataFrame where age is greater than 30.
What to look for: Everyday Pandas fluency and boolean indexing without overcomplicating it.
39. Write a function to count the frequency of each word in a string.
What to look for: String handling and a dictionary (or Counter) for the count, plus a thought about case and punctuation.
Grade partial answers generously. A data scientist who writes clean, readable code and names the edge case they did not have time to handle is often a better hire than one who pastes a perfect but unexplained solution. For a hands-on shortlist round, Testlify live coding projects run in a proctored editor, and the SQL test covers query skills before the interview.
Which business and product sense questions matter for data scientists?
Business and product sense questions matter because a model only creates value when it changes a decision. These three questions show whether a candidate starts from the business problem or from the algorithm.
40. Daily active users dropped 10% last week. How would you investigate?
What a strong answer covers: Confirm the data is right, then segment by platform, region, new vs returning users and recent releases, and form hypotheses before digging. Look for structure, not a guess.
41. Which metric would you use to judge a new recommendation feature?
What a strong answer covers: A primary metric tied to the goal (such as purchases per session), a guardrail metric (such as returns or unsubscribes) and how they would test it.
42. Can you give an example of a real business problem you solved with data?
What a strong answer covers: The problem, the data, the method, and a result in money, hours or customers. Red flag: A great model nobody used.
Which behavioral questions reveal a data scientist's real experience?
Behavioral questions reveal real experience because they make a candidate tell a story with specifics: real datasets, real stakeholders and a clear account of what their work changed. Theory shows what someone knows; these eight show what they have done when a project went sideways.
43. Tell me about the most challenging data project you shipped. How did you approach it, and what was the outcome?
What to look for: A clear problem, the hardest blocker and a measurable result.
Sample answer: "I built a churn model for a telecom client. The data had missing values and imbalanced classes, so I cleaned it, engineered usage features and used oversampling. The final model flagged at-risk customers early enough for the retention team to act."
44. Describe a time you explained a complex finding to a non-technical stakeholder.
What to look for: Plain language, a visual, and a check that the listener understood.
Sample answer: "I explained ensemble models to a client by comparing them to asking several experts and averaging their views. I showed one chart of the error drop and tied it to fewer missed orders."
45. Describe a situation with conflicting priorities or a tight deadline. How did you manage it?
What to look for: Breaking work into milestones, agreeing priorities with stakeholders and protecting quality.
Sample answer: "Three teams wanted analysis in the same sprint. I listed each request with its deadline and business impact, agreed the order with my manager and shipped a first version for the most urgent one."
46. Tell me about a significant data quality issue. How did you find and fix it?
What to look for: Detective work, a fix at the source, and a check to stop it coming back.
Sample answer: "Duplicate records were skewing results. EDA showed odd counts in a few fields, I used fuzzy matching to remove duplicates and worked with data engineering to add validation at ingestion."
47. Tell me about a time your analysis pointed the business the wrong way, or a model underperformed in production. What did you do next?
What to look for: Ownership, a root cause and what changed in their process.
48. Describe a time you traded model accuracy for interpretability or speed.
What to look for: A real constraint (regulation, latency, stakeholder trust) and a reasoned choice.
49. How have you handled sensitive or personal data, and how did you protect privacy?
What to look for: Access controls, anonymization, data minimization and awareness of rules such as GDPR, plus how they checked models for unfair outcomes.
50. How do you keep up with a field that moves this fast?
What to look for: Named sources, recent projects or courses, and something they built or tried in the past six months.
Vague answers are the tell. A senior data scientist names the dataset, the metric, the constraint and the trade-off they accepted. Someone padding a resume stays abstract because there is no real project underneath the words.
How should questions change for junior vs senior data scientists?
Questions for junior data scientists should check fundamentals and clean code, while questions for senior data scientists should check trade-offs, production experience and business impact. Use the same groups for both, but change the mix and the bar.
Level | Focus your questions on | Example picks | What a strong candidate shows |
|---|---|---|---|
Junior (0 to 2 years) | Statistics basics, core ML concepts, Python and SQL | 1, 9, 11, 23, 35, 36 | Correct fundamentals, clean code, curiosity |
Mid-level (2 to 5 years) | Model choice, metrics, data handling at scale, A/B tests | 3, 14, 16, 22, 27, 40 | Sound choices with reasons, owns projects end to end |
Senior and lead (5+ years) | Production models, drift, LLM evaluation, stakeholder influence | 31, 32, 41, 42, 47, 48 | Business impact in numbers, mentors others, knows when not to build a model |
For the full picture of the role, pair this with a clear data scientist job description.
How do you score answers without a data science background?
Answers are easiest to score with a rubric, so you judge evidence instead of impressions. You do not need to build models yourself to spot a strong answer; you need a consistent scale and a few things to listen for. Guidance from the US Office of Personnel Management on structured interviews makes the same point: ask every candidate the same questions, score against set benchmarks and have panel members rate on their own first.
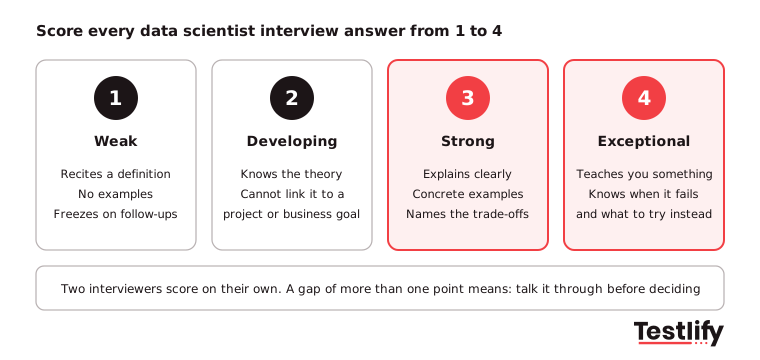
Rate each answer from 1 to 4 across the skill areas in the first table, and weight business sense as heavily as the math, because that is where many data hires struggle on the job.
- 1 (weak): Recites a definition, gives no examples, freezes on follow-ups.
- 2 (developing): Knows the theory but cannot connect it to a real project or a business goal.
- 3 (strong): Explains clearly, gives concrete examples, names the trade-offs.
- 4 (exceptional): Teaches you something, including when an approach fails and what they would try instead.
Red flags to note on the scorecard:
- Accuracy as the only metric, even on imbalanced data.
- No questions about the business goal before choosing a method.
- Copy-paste code they cannot explain.
- Every past project described with "we" and never "I".
Have two interviewers score on their own, then compare. When their numbers differ by more than a point, that gap is usually where the real signal sits, so talk it through before you decide. A shared interview scorecard and a structured interview format keep this consistent across panels.
Pair the interview score with the skills test score, and you have an evidence-based call, not a popularity contest. For more on why tested skills beat resumes, see our take on prioritizing skills over degrees and the benefits of pre-hiring assessments.
Key takeaway: The best sign of a data scientist's success on the job is not the degree or the Kaggle rank. It is whether they can connect a model to a decision and explain why it might be wrong. Test for that first, then interview to confirm it.
Hire data scientists with confidence
Start every data hire with proof of skill. Send candidates a role-based data scientist assessment or the Python for data science test, add a live coding project for the shortlist, and walk into the interview already knowing who can do the work. Testlify's 20+ proctoring checks keep remote test results honest.
Browse the 3,500+ tests in the Testlify test library, start a 7-day free trial with no credit card, or book a demo to set up a test-then-interview flow for your team.
Frequently asked questions (FAQs)
Related resources
View all
HR & recruitment
40 Interview questions to ask while hiring a cloud engineer
HR & recruitment
Contrast bias: Definition, examples, and how to prevent It in hiring
HR & recruitment
Management Tests: How to Conduct Them and Choose the Right Platform
HR & recruitment
How to recruit top talent using customer service assessment
HR & recruitment
Pros and cons of using mechanical tests
HR & recruitment
Mechanical Aptitude Test: How to Use It to Cut Turnover (2026)
Get started.
Hire on proof, not resumes.
Run your first skills-based assessment free — no credit card required.