
How to hire a data scientist: a 9-step guide for 2026
Hire a data scientist in 9 steps: define the problem, pick the profile, test Python, SQL and statistics, interview on a rubric, offer fast.
Knowing how to hire a data scientist starts with one decision most teams skip: which business question the hire will answer. Define that problem, check that your data can support it, then test Python, SQL, statistics and machine learning before any interview, run structured interviews against one rubric, and make the offer within days of the final round.
TL;DR / Key Takeaways
- To hire a data scientist, define the business problem first, pick the matching profile, test core skills before interviews, score every interview on one rubric and offer fast.
- Data scientists, data analysts, data engineers and machine learning engineers are different hires. Many teams that post for a data scientist really need an analyst or a data engineer first.
- Hire a data scientist only when you have usable data, a question worth modeling and someone who will act on the answer.
- Screen on skills, not resumes: a short test on Python, SQL, statistics and machine learning, then a take-home of no more than 2 to 4 hours.
- The US Bureau of Labor Statistics puts median data scientist pay at $120,230 (May 2025) and projects 35% job growth from 2025 to 2035.
- Strong candidates juggle several offers, so aim to close within about 3 to 5 weeks of first contact.
 ChatGPT
 Gemini
 Claude
 Grok
 Perplexity
What does a data scientist do?
A data scientist turns raw data into decisions. The role covers collecting and cleaning data, finding patterns, building and testing statistical and machine learning models, and explaining the results to people who will act on them. The O*NET profile for data scientists lists the same core: data mining, modeling, visualization and reporting findings.
A good data scientist mixes three skill sets: math and statistics, programming, and business sense. Most candidates are strong in two of the three. That gap is why hiring for this role goes wrong so often.
Data science also covers several neighboring roles. Hiring the wrong one is the most common and most expensive mistake.
Role | Main job | Core tools | Hire this role when |
|---|---|---|---|
Data analyst | Explains what happened with reports and dashboards | SQL, Excel, Tableau, Power BI | You need visibility and reporting |
Data scientist | Predicts what will happen and tests what works | Python or R, statistics, scikit-learn | You need experiments, forecasts or models |
Data engineer | Builds the pipelines and warehouse everyone uses | SQL, Spark, Airflow, cloud data platforms | Your data is scattered or untrusted |
Machine learning engineer | Puts models into production and keeps them running | Python, MLOps, cloud ML services | Models must serve live products at scale |
BI analyst | Builds business reporting for leaders | BI tools, SQL | Leaders need a single view of key metrics |
Other titles you will see include research scientist, applied scientist, product data scientist and data product manager. Read the work behind the title, not the title itself. For data engineering hires, see our guide to big data engineering hiring.

When should you hire a data scientist?
A company should hire a data scientist when three things are true: it has enough usable data, it has a business question that modeling can answer, and someone is ready to act on the result. Hire too early and your new data scientist spends months building pipelines instead of models, which is a common reason they leave.
Run this quick readiness check before you open the role:
- Data: Your key data sits in one warehouse or database, with tables people trust.
- Question: You can name the decision the hire will improve, such as churn, pricing, fraud or demand forecasting.
- Owner: A leader will use the output and change a process because of it.
- Support: Someone owns data pipelines, or the role includes that work and the job description says so.
If the data check fails, hire a data engineer or analytics engineer first. If you mostly need dashboards, hire a data analyst.
When the conditions are right, a data scientist pays back in several ways:
- Better decisions: Analysis of large data sets replaces gut feel on pricing, product and spend.
- New revenue: Models find untapped segments, cross-sell openings and new product ideas.
- Lower cost: Forecasts and automation cut waste in operations, inventory and support.
- Customer insight: Behavior data shows why customers buy, stay or leave.
- Risk control: Models flag fraud, credit risk and anomalies before they become losses.
How to hire a data scientist in 9 steps
The best process for how to hire a data scientist runs in nine steps: define the problem, pick the profile, check data readiness, write the job description, source, screen with skills tests, interview on a rubric, decide and offer fast, and onboard for 90 days. Steps 6 and 7 carry most of the decision.
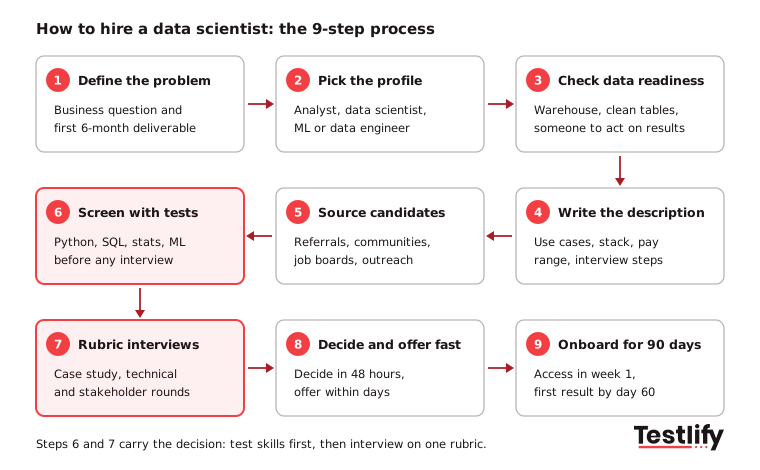
- Define the business problem: Write down the question the hire will answer and what they should deliver in the first six months. This decides seniority and profile.
- Pick the profile: Choose analytics-leaning, experimentation-focused or machine-learning-focused. A job description that blends all three attracts no one.
- Check data readiness: Confirm the data and tooling exist, using the checklist above.
- Write the job description: List real use cases, the tech stack, the pay range and the interview steps. Detail helps good candidates decide to apply.
- Source candidates: Combine referrals, data science communities, job boards and direct outreach. Keep a pool of strong people who are not looking today.
- Screen with skills tests: Test Python, SQL, statistics and machine learning before the first interview, so interview time goes only to people who can do the work.
- Interview with a rubric: Run a case study, a technical round and a stakeholder round, each scored on the same criteria.
- Decide and offer fast: Hold the debrief within 48 hours of the final round, check references with past managers, and send the offer within days, not weeks.
- Onboard for 90 days: Give access in week one and a scoped first project with a visible result by day 60.
Pro tip: Ask the hiring manager to write the first six-month deliverable before anything else. When the manager cannot write it, the role is not ready to open.
What skills should you look for in a data scientist?
A data scientist needs six skills: programming, SQL and data wrangling, statistics, machine learning, communication, and business judgment. The first four can be tested with short skills tests. The last two show up best in a case study and a stakeholder interview.
Skill | What good looks like | How to test it |
|---|---|---|
Python or R | Clean, readable code with Pandas, NumPy and scikit-learn | Python for data science test, coding task |
SQL and data wrangling | Joins, window functions, handling missing and duplicate data | SQL test, data cleaning task |
Statistics | Hypothesis tests, regression, A/B test design, knowing when a result is not trustworthy | statistics and probability test |
Machine learning | Picks a simple model first, validates properly, explains trade-offs | machine learning test, model walkthrough |
Data visualization | Charts that make one point clearly | data visualization test |
Critical thinking | Frames the question before reaching for tools | critical thinking test, case study |
Some tools matter only for some teams. Spark matters when data is large and distributed. NLP matters for text-heavy products such as reviews, support tickets or search. Cloud data platforms such as BigQuery, Snowflake or Redshift matter if your warehouse runs on them. Test these only when the job uses them.
Soft skills decide whether the work gets used. Look for clear communication with non-technical people, curiosity about the business, teamwork with engineers and product managers, and the honesty to say when a model should not be trusted.
What should a data scientist job description include?
A data scientist job description should include the business problems the role will work on, the tech stack, must-have versus nice-to-have skills, the pay range, the work setup and the interview steps. Keep must-haves short. Every extra requirement shrinks the pool without improving it.
Use this outline, then adapt the full data scientist job description template to your team.
Job title: Data Scientist (add the focus if it matters, such as Data Scientist, Experimentation)
Summary: We are looking for a data scientist to turn large, complex data into clear recommendations that shape product, operations and revenue decisions. You will work with product managers, engineers and business leaders to frame the right questions, build and test models, and explain what the results mean.
Responsibilities:
- Collect, clean and analyze large data sets to find patterns and trends
- Build, test and improve predictive models for problems such as churn, demand or risk
- Design and analyze A/B tests and other experiments
- Build and maintain data pipelines with the data engineering team
- Explain findings to technical and non-technical audiences through reports, dashboards and presentations
- Keep up with new methods and adopt them when they clearly beat current ones
Requirements:
- Strong Python or R, with Pandas, NumPy and scikit-learn
- Solid statistics: hypothesis testing, regression and experimental design
- Advanced SQL on large relational databases
- Experience with machine learning frameworks such as scikit-learn, TensorFlow or PyTorch
- Clear written and spoken communication
- Nice to have: cloud data platforms (BigQuery, Snowflake or Redshift), MLOps tools, domain experience
Benefits to name: Pay range, remote or hybrid setup, learning budget and conference time, modern data infrastructure, and the business problems the hire will own.
Skip the degree filter where you can. Many strong data scientists hold a bachelor's degree plus a few years of hands-on work, and a PhD requirement removes most of the market for roles that do not need research.
Where can you find data scientist candidates?
Data scientist candidates come from five main channels: employee referrals, data science communities, specialist and general job boards, direct outreach on LinkedIn, and a talent pool you keep warm. The best candidates are often not looking, so outreach and referrals matter more here than for most roles.
- Employee referrals: Ask your engineers and analysts who they rate. A referral bonus for data roles is usually worth it.
- Communities and events: Kaggle, GitHub, PyData and local meetups show real work, not just resumes.
- Job boards: LinkedIn, Indeed, Glassdoor, Dice and specialist boards such as DataJobs reach active candidates.
- Direct outreach: Search by skills and current work, not title. Strong people often sit under titles such as applied scientist, analytics engineer, decision scientist or ML engineer.
- Talent pool: Keep strong runners-up and past applicants in your ATS and contact them when the next role opens.
- Employer brand: Write about your data problems and team, so candidates know what the work looks like before they apply.
Use short, specific messages. These templates work as a starting point.
Social post: We are hiring a Data Scientist to help us answer [business question] with [data source]. Python, SQL and experiments, with real impact on [team or product]. Apply here: [link] #DataScience #Hiring
Outreach email: Subject: Data Scientist role at [Company]: [one-line problem]. Hi [Name], I saw your work on [project or post] and thought of a problem we are working on: [business question]. We are hiring a Data Scientist to own it, working with [team] on [stack]. The process is a short skills test, one case study and two interviews, finished within about three weeks.
Open to a 20-minute call this week? [Your name], [Title]
Rejection email: Hi [Name], thank you for the time you put into our Data Scientist process. We have decided to move forward with another candidate whose experience is closer to what this role needs right now. We valued your [specific strength] and would like to keep in touch for future data roles. Best, [Your name]
How do you assess data scientist candidates fairly?
Data scientist candidates are best assessed in four stages, each scored on the same rubric: a short skills test, a take-home or live case, a technical interview and a stakeholder round. Agree on what a good answer looks like before the first candidate starts, so interviewers compare evidence instead of impressions.
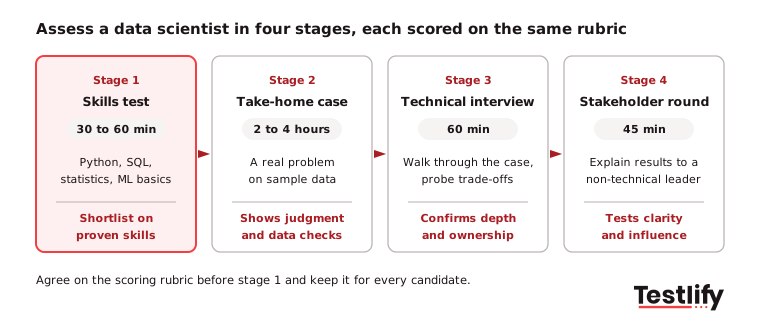
1. Skills test first: A pre-interview test checks the basics fast and in the same way for everyone. A data scientist test covering data science fundamentals, machine learning, data visualization and data analysis takes 10 minutes for 8 questions. Combine it with Python, SQL and statistics tests for a full screen of 30 to 60 minutes.
2. A short take-home or live case: Give a real problem on sample or anonymized data. Recruiting firm KORE1 advises keeping take-homes to 2 to 4 hours, or paying for anything longer, and Underdog's 2026 startup hiring guide reports that 2 to 3 hours is enough. Judge the reasoning, the data checks and whether the conclusion makes business sense, not model complexity.
3. Technical interview: Ask the candidate to walk through the case and a past project end to end, from data preparation to model choice, validation and deployment.
4. Stakeholder round: Ask the candidate to explain a model they built to a leader with no data background. This round shows whether their work will get used.
Score each stage on a shared interview scorecard with criteria such as data fluency, statistical judgment, model choice, business framing and communication.
Fairness matters in remote screening too. Use proctoring and anti-cheating checks on unsupervised tests, and keep a person in every rejection decision. If you use AI to score or rank candidates for jobs in New York City, Local Law 144 on automated employment decision tools requires a yearly bias audit and notice to candidates.
Key takeaway: A short skills test before interviews and one rubric across every stage do more for quality of hire than any extra interview round.
What should you ask in a data scientist interview?
A data scientist interview should test four things: past project depth, statistical judgment, communication with non-technical people and fit with how your team works. These ten questions cover all four. For a longer bank by topic, see our interview questions for data scientists.
# | Question | What it reveals | What a strong answer includes |
|---|---|---|---|
1 | Describe a project where you used statistical analysis. | Applied statistics | The problem, the data, the method, the result and what went wrong |
2 | How do you handle missing or incomplete data? | Real-world data sense | Checks how much is missing and why, then imputes or drops with clear trade-offs |
3 | Walk me through a machine learning model you built and how it was used. | ML depth and ownership | Why that model, how it was validated, the business metric it moved |
4 | Tell me about a time you explained findings to a non-technical audience. | Communication | Plain language, one clear chart, a decision that followed |
5 | How have you worked with a very large data set? | Scale | Sampling, distributed tools such as Spark, efficient queries |
6 | Which analytics tools and languages are you strongest in, and where did you use them? | Tool fit | Specific projects, not a list of tools |
7 | Give an example of using data to improve a customer or stakeholder experience. | Business impact | The insight, the change made and the measured outcome |
8 | A model is 95% accurate. Should we ship it? | Statistical judgment | Asks about base rates, precision and recall, and the cost of errors |
9 | Tell me about a time your first analysis was misleading. How did you catch it? | Honesty and rigor | A specific error, how they found it and what they changed |
10 | Why data science, and what are you learning now? | Motivation | Real curiosity and recent learning tied to the work |
Add one or two technical checks for depth, such as explaining cross-validation, the difference between supervised and unsupervised learning, or what a p-value does and does not tell you. Keep every question the same for every candidate, as in a structured interview.
How much does it cost to hire a data scientist?
Hiring a data scientist in the US costs a median salary of $120,230 a year, according to the US Bureau of Labor Statistics (May 2025 data). Add bonus, equity, benefits, recruiting costs and tools on top. BLS also projects 35% employment growth from 2025 to 2035, with about 24,800 openings a year, so pay pressure is not going away.
Cost driver | Effect on cost |
|---|---|
Seniority | The biggest driver. Senior and staff roles cost far more than entry level. |
Specialization | Machine learning, NLP and applied generative AI skills carry a premium. |
Location | Major tech hubs such as San Francisco and New York pay the most, though remote hiring narrows the gap. |
Industry | Technology and finance usually pay above healthcare, education and non-profits. |
Engagement type | Contractors suit a defined project; full-time hires suit ongoing core work. |
Set a pay range before you post, and anchor offers near the middle of it. Raising the range mid-search costs you the candidates who already saw the old number.
How do you make an offer a data scientist will accept?
A data scientist accepts an offer that arrives fast, pays in line with the market and shows meaningful work. Good candidates often hold several offers, so speed matters as much as pay. According to KORE1's 2026 hiring guide, a typical data science time-to-hire is 18 to 26 days.
- Debrief within 48 hours: Each interviewer shares scored evidence. When opinions conflict, go back to the rubric, not the loudest voice.
- Pre-approve the budget: Agree on the pay range and sign-off before the final round so nothing waits on approvals.
- Sell the problem: Explain the questions they will own, the data they will use and who will act on their work.
- Be clear on equity: Explain vesting and what is uncertain in plain terms.
- Track stage time: Measure how long candidates sit in each stage and cut the slowest one. Our guide to reducing time to hire covers the levers.
How should you onboard a new data scientist?
A new data scientist should get system access in week one, a scoped first project by week two and a visible result by day 60. Stalled starts usually trace back to missing data access and a vague mandate, not to the hire.
- Days 1 to 30: Access to data, tools and code; meet stakeholders; agree the first project and its success metric. Assign a mentor.
- Days 31 to 60: Deliver a first analysis or model that a stakeholder uses. Review progress and give feedback.
- Days 61 to 90: Own an area end to end, present results to leadership and set goals for the next quarter.
Keep learning going after onboarding with time for training, conferences and shared reviews of each other's work. Use an onboarding checklist so nothing is missed, and see how to build a successful data science team as the team grows. A strong team also shares good data governance: privacy, security and data quality habits that keep results reliable.
How to hire a data scientist without the common mistakes
The most common mistakes when hiring a data scientist are hiring before the data is ready, writing a "unicorn" job description and running a slow, unstructured process. Each one costs months and good candidates.
- Hiring too early: Without usable data, the hire builds pipelines instead of models and often leaves.
- The unicorn job description: Asking for analytics, research, engineering and MLOps in one person attracts no one.
- Over-weighting credentials: A PhD or a famous employer is not proof of skill. Test skills directly.
- Long take-homes: Multi-day assignments test free time, not ability, and strong candidates drop out.
- No rubric: Unstructured interviews produce opinions that are hard to compare and easy to bias.
- Ignoring communication: A model nobody understands does not change any decision.
- Slow offers: Every extra week after the final round raises the chance of losing the candidate.
Hire your next data scientist with Testlify
Testlify helps hiring teams screen data scientists on proven skills before the first interview. Choose from 3,500+ tests, including Python, SQL, statistics and machine learning, or generate a custom assessment from your job description in under a minute. Live coding supports 45+ programming languages, 20+ proctoring checks protect remote tests, and results sync with 100+ ATS integrations. Need expert interviewers too? Interview-as-a-Service matches vetted domain experts to your roles.
Start a 7-day free trial with no credit card, or book a demo to see a data science assessment built for your team.
Frequently asked questions
Content Writer
Yashika Khandelwal is a Content Writer with 3+ years of experience creating research-backed content on hiring, talent assessment, and HR technology. She is a registered Organizational Psychologist and subject matter expert who combines behavioral science with practical recruitment insights to produce accurate, evidence-based content.
LinkedInRelated resources
View all
HR & recruitment
Hiring a marketing manager: a comprehensive guide for businesses
HR & recruitment
How to hire a VP of sales
HR & recruitment
How to recruit an intern (2026)
HR & recruitment
How to hire a database administrator: a 2026 guide
HR & recruitment
How to hire a web developer – a complete guide
HR & recruitment
Google sheets questions for business accountant hiring
Get started.
Hire on proof, not resumes.
Run your first skills-based assessment free — no credit card required.